H100 · H200 · RTX 5090 · RTX 4090
Dedicated GPU servers for AI teams, running in 48 hours
Lease H100, H200, RTX 5090 and RTX 4090 stations with root access and one monthly rate. We source the hardware, tune the stack and replace failed parts, so your team stays on the workload.
30 minute call with an engineer. Written spec and fixed price before you commit.
- GPUs under management
- 0+
- Fleet availability
- 0.0%
- Engineering on call
- 0/7

Services
Three ways to get compute
Lease capacity by the month, buy the hardware outright, or have us design and run the whole system.


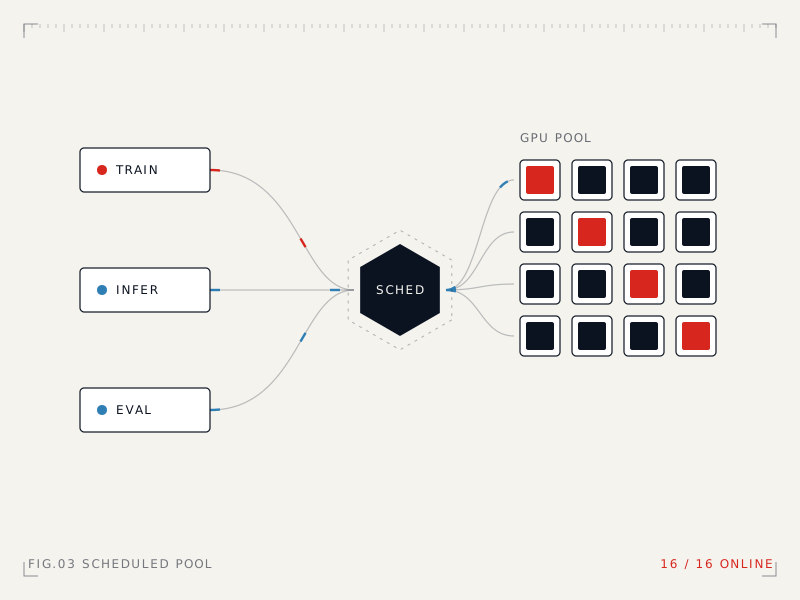
About us
Compute infrastructure, delivered as a working system
Axionca sits between the model and the metal. We source and rack the accelerators, tune the stack that runs on them, and stay accountable for uptime. Your team spends its time on the workload instead of the hardware.
- Current generation NVIDIA accelerators, racked and ready
- Dedicated or on demand capacity with no long procurement cycle
- Interconnect, storage and cooling specified for the workload
- Monitoring, patching and hardware replacement handled by us

You bring the model and the deadline. We keep the metal running, so every hour on the clock goes to training, not to hardware.
Why Axionca
Engineers on the call, not account managers
The people who scope your configuration are the people who rack it and answer when it breaks.
No capital tied up
Lease the capacity you need this quarter instead of financing a fleet you will outgrow.
Provisioned in 48 hours
Stations from our standing inventory are racked, imaged and handed over within two business days.
One rate, no surprises
One price per configuration. No egress fees, no per hour rounding, no support tiers.
Yours to control
Root access, your images, your orchestration. We keep the floor running and stay out of your stack.
Pricing
Pick the accelerator. We handle everything under it.
A single station for a research team, or a full rack for a training run. Every configuration ships with NVMe scratch, private networking and root access.
RTX 5090
$1,180/ mo24 core CPU · 128 GB RAM · 4 TB NVMe
- Memory
- 32 GB GDDR7
- Best for
- Fine tuning, rendering and research on one node
RTX 4090
$860/ mo16 core CPU · 96 GB RAM · 2 TB NVMe
- Memory
- 24 GB GDDR6X
- Best for
- Inference endpoints, prototyping and CI for models
H100 SXMPopular
$3,940/ moDual 32 core EPYC · 512 GB RAM · NVLink
- Memory
- 80 GB HBM3
- Best for
- Training across GPUs and large batch inference
H200 SXM
$5,620/ moDual 32 core EPYC · 1 TB RAM · NVLink
- Memory
- 141 GB HBM3e
- Best for
- Frontier scale training and long context serving
Indicative monthly rates for dedicated stations on a three month term. Hourly on demand and annual reserved pricing on request.
Request a quoteWhat we do
From a single station to a managed cluster
Three practices, one team. Most clients start with leased capacity and grow into hardware supply and managed operations.
GPU station leasing
Dedicated RTX 5090, RTX 4090, H100 and H200 stations with root access, private networking and NVMe scratch storage.
Cluster builds
Training clusters across nodes with NVLink or InfiniBand fabric, shared storage and job scheduling configured for your stack.
Hardware supply
Workstations, servers, accelerators and spares, sourced, burned in and shipped with warranty and replacement cover.
Hybrid cloud design
Burst to public cloud for peaks while steady workloads run on owned or leased capacity at a fraction of the cost.
Security and compliance
Isolated tenancy, encrypted volumes, scoped credentials and audit logging aligned to SOC 2 controls.
Managed operations
Monitoring, driver and firmware patching, capacity planning and hardware replacement, without paging your team.
How it works
From first call to first training run
- 01
Scoping call
We size the workload (model, batch, memory ceiling, throughput target) and tell you what hardware it actually needs.
- 02
Fixed spec and price
You get a written spec and a fixed price. Stations are then racked, burned in and benchmarked before handover.
- 03
Run and scale
We watch the fleet and swap failed parts. When the workload grows, capacity is added without a new procurement round.
Clients
What teams say after the first training run
We had H100 capacity running training jobs four days after the first call. Our previous vendor quoted eleven weeks for the same configuration.
Axionca specified the fabric and storage properly, which is why our run across nodes scales instead of stalling. That advice was worth more than the hardware discount.
One rate per station, no egress line items, and a human answers when a card throws errors at 2am. It is a boring relationship, which is exactly what we wanted.
FAQ
Questions we get on every scoping call
Something not covered here? Ask us directly. An engineer answers, usually the same day.
Configurations held in standing inventory (RTX 5090, RTX 4090 and H100 stations) are typically racked, imaged and handed over within 48 hours. H200 and large clusters depend on current allocation; we give you a firm date on the scoping call.
Get started
Tell us the workload.We will tell you the hardware.
Bring the model, batch size and throughput target. On a 30 minute call you get a configuration, a price and an availability date. No pitch deck.
- Written spec and fixed price before you commit
- Hardware replacement included with every lease
- Reply from an engineer within one business day
- info@axionca.com
- Phone
- 587-713-4758
- Office
- 10th Floor, 10055-106 Street NW, Edmonton, AB T5J 2Y2, Canada
- Hours
- Mon to Fri, 9:00 to 19:00. Closed weekends.